Biography

Hi! I’m Yiwen He (何翌闻), an undergraduate student in Software Engineering at Nanjing University’s Software Institute, enrolled in 2024.

I’m currently interested in Multimodal Intelligence, World Models, and Agentic AI.✨
Education

Nanjing University emblem

Nanjing University

Software Institute, China

B.E. in Software Engineering

Sep. 2024 – Present

Research Collaborations

DevOps+ Research Laboratory

Oct. 2025 – Present

Software Institute, Nanjing University

With Hongyu Kuang.

Sentiment analysis of long software development discussion threads in the Kubernetes open-source community.
Jul. 2025 – Oct. 2026

School of Intelligence Science and Technology, Nanjing University

With Jiaheng Liu.

Multimodal evaluation, with an emphasis on video understanding and editing benchmarks.
LAMDA Group

Feb. 2026 – Oct. 2026

School of Artificial Intelligence, Nanjing University

With Tian-Shuo Liu (Ph.D. student) and Yang Yu.

A large-scale virtual human model for pharmacokinetic and pharmacodynamic (PK/PD) simulation.

The project advanced to the national stage of the China International College Students’ Innovation Competition.
Publications

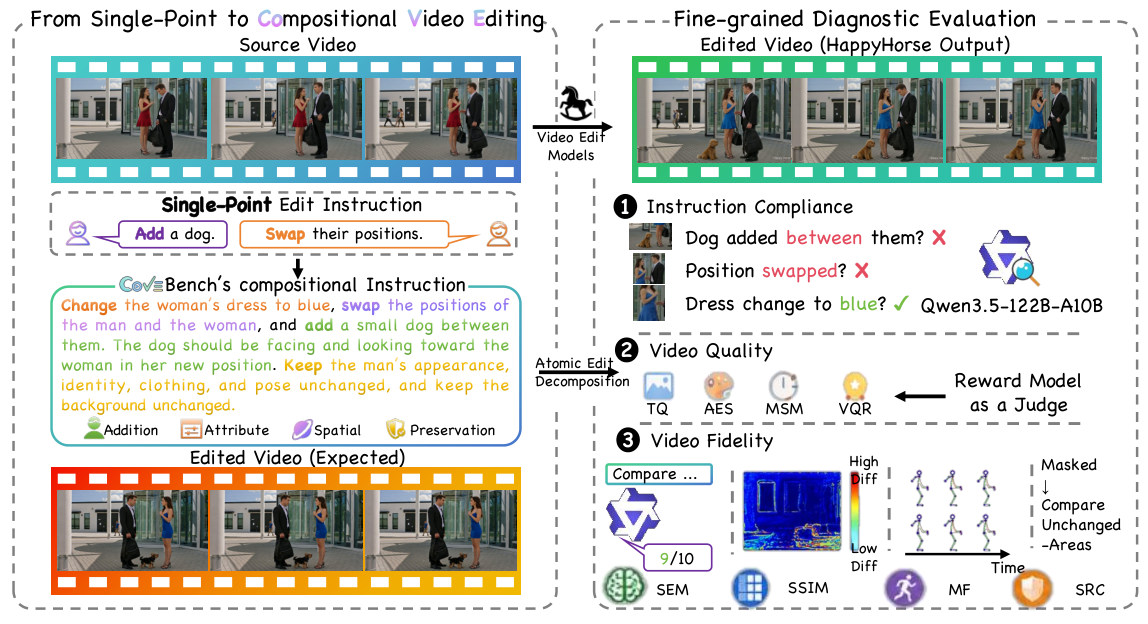
CoVEBench 复合视频编辑指令与诊断评测框架

arXiv 2026

CoVEBench: Can Video Editing Models Handle Complex Instructions?

Jiangtao Wu*, Jiaming Wang*, Yiwen He*, Yuanxing Zhang, Shihao Li, Dunyuan Liu, Xuedong Zhao, Jialu Chen, Zekun Moore Wang, Jiaheng Liu

Co-first author

  • Compositional video editing. 626 multi-point instructions and 9,990 diagnostic checks evaluate complex edits alongside source preservation.
  • A measurable gap. Across 10 models, the best union accuracy is 56.89%, highlighting the difficulty of combining accurate edits with visual realism.
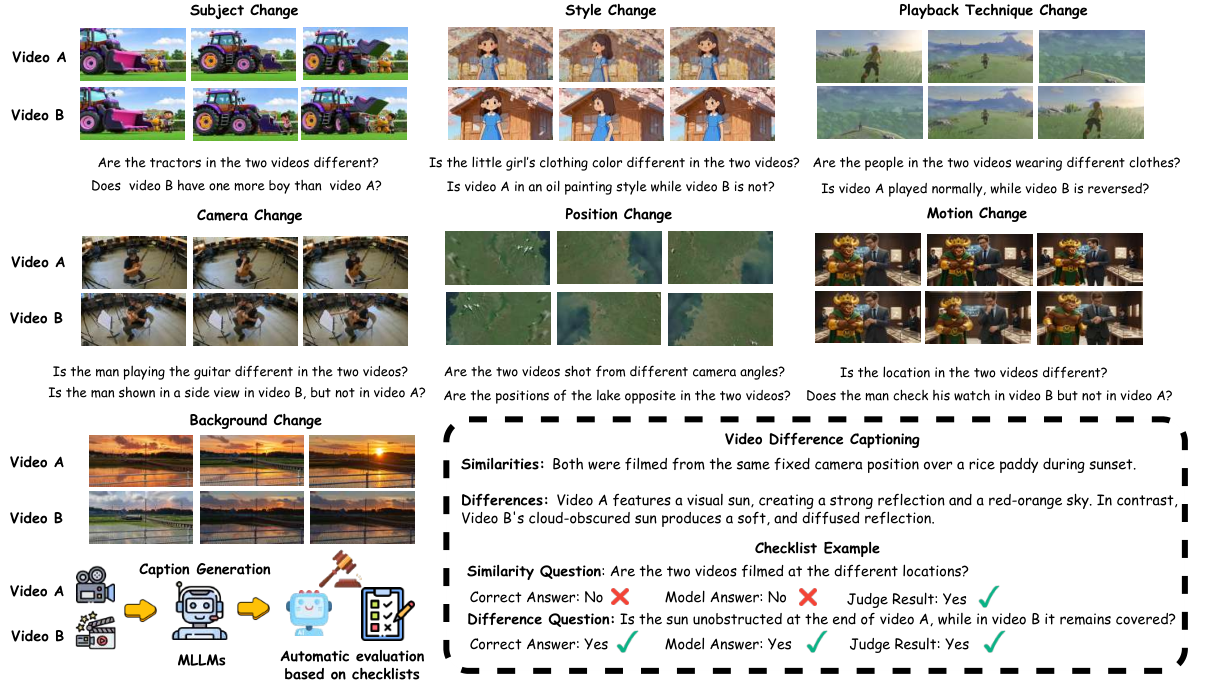
ViDiC 七类视频差异与双清单评测示例

NeurIPS 2026 (Evaluations & Datasets Track)

ViDiC: Video Difference Captioning

Jiangtao Wu*, Shihao Li*, Zhaozhou Bian*, Jialu Chen, Yiwen He, Runzhe Wen, An Ping, Jiakai Wang, Yuanxing Zhang, Jiaheng Liu

Co-author

  • Video difference captioning. Introduces a 1,000-pair benchmark with 3,720 comparative checks across seven semantic dimensions.
  • Dual-checklist evaluation. Separates missed differences from hallucinated changes, revealing weaknesses in temporal reasoning, camera work, and playback understanding.
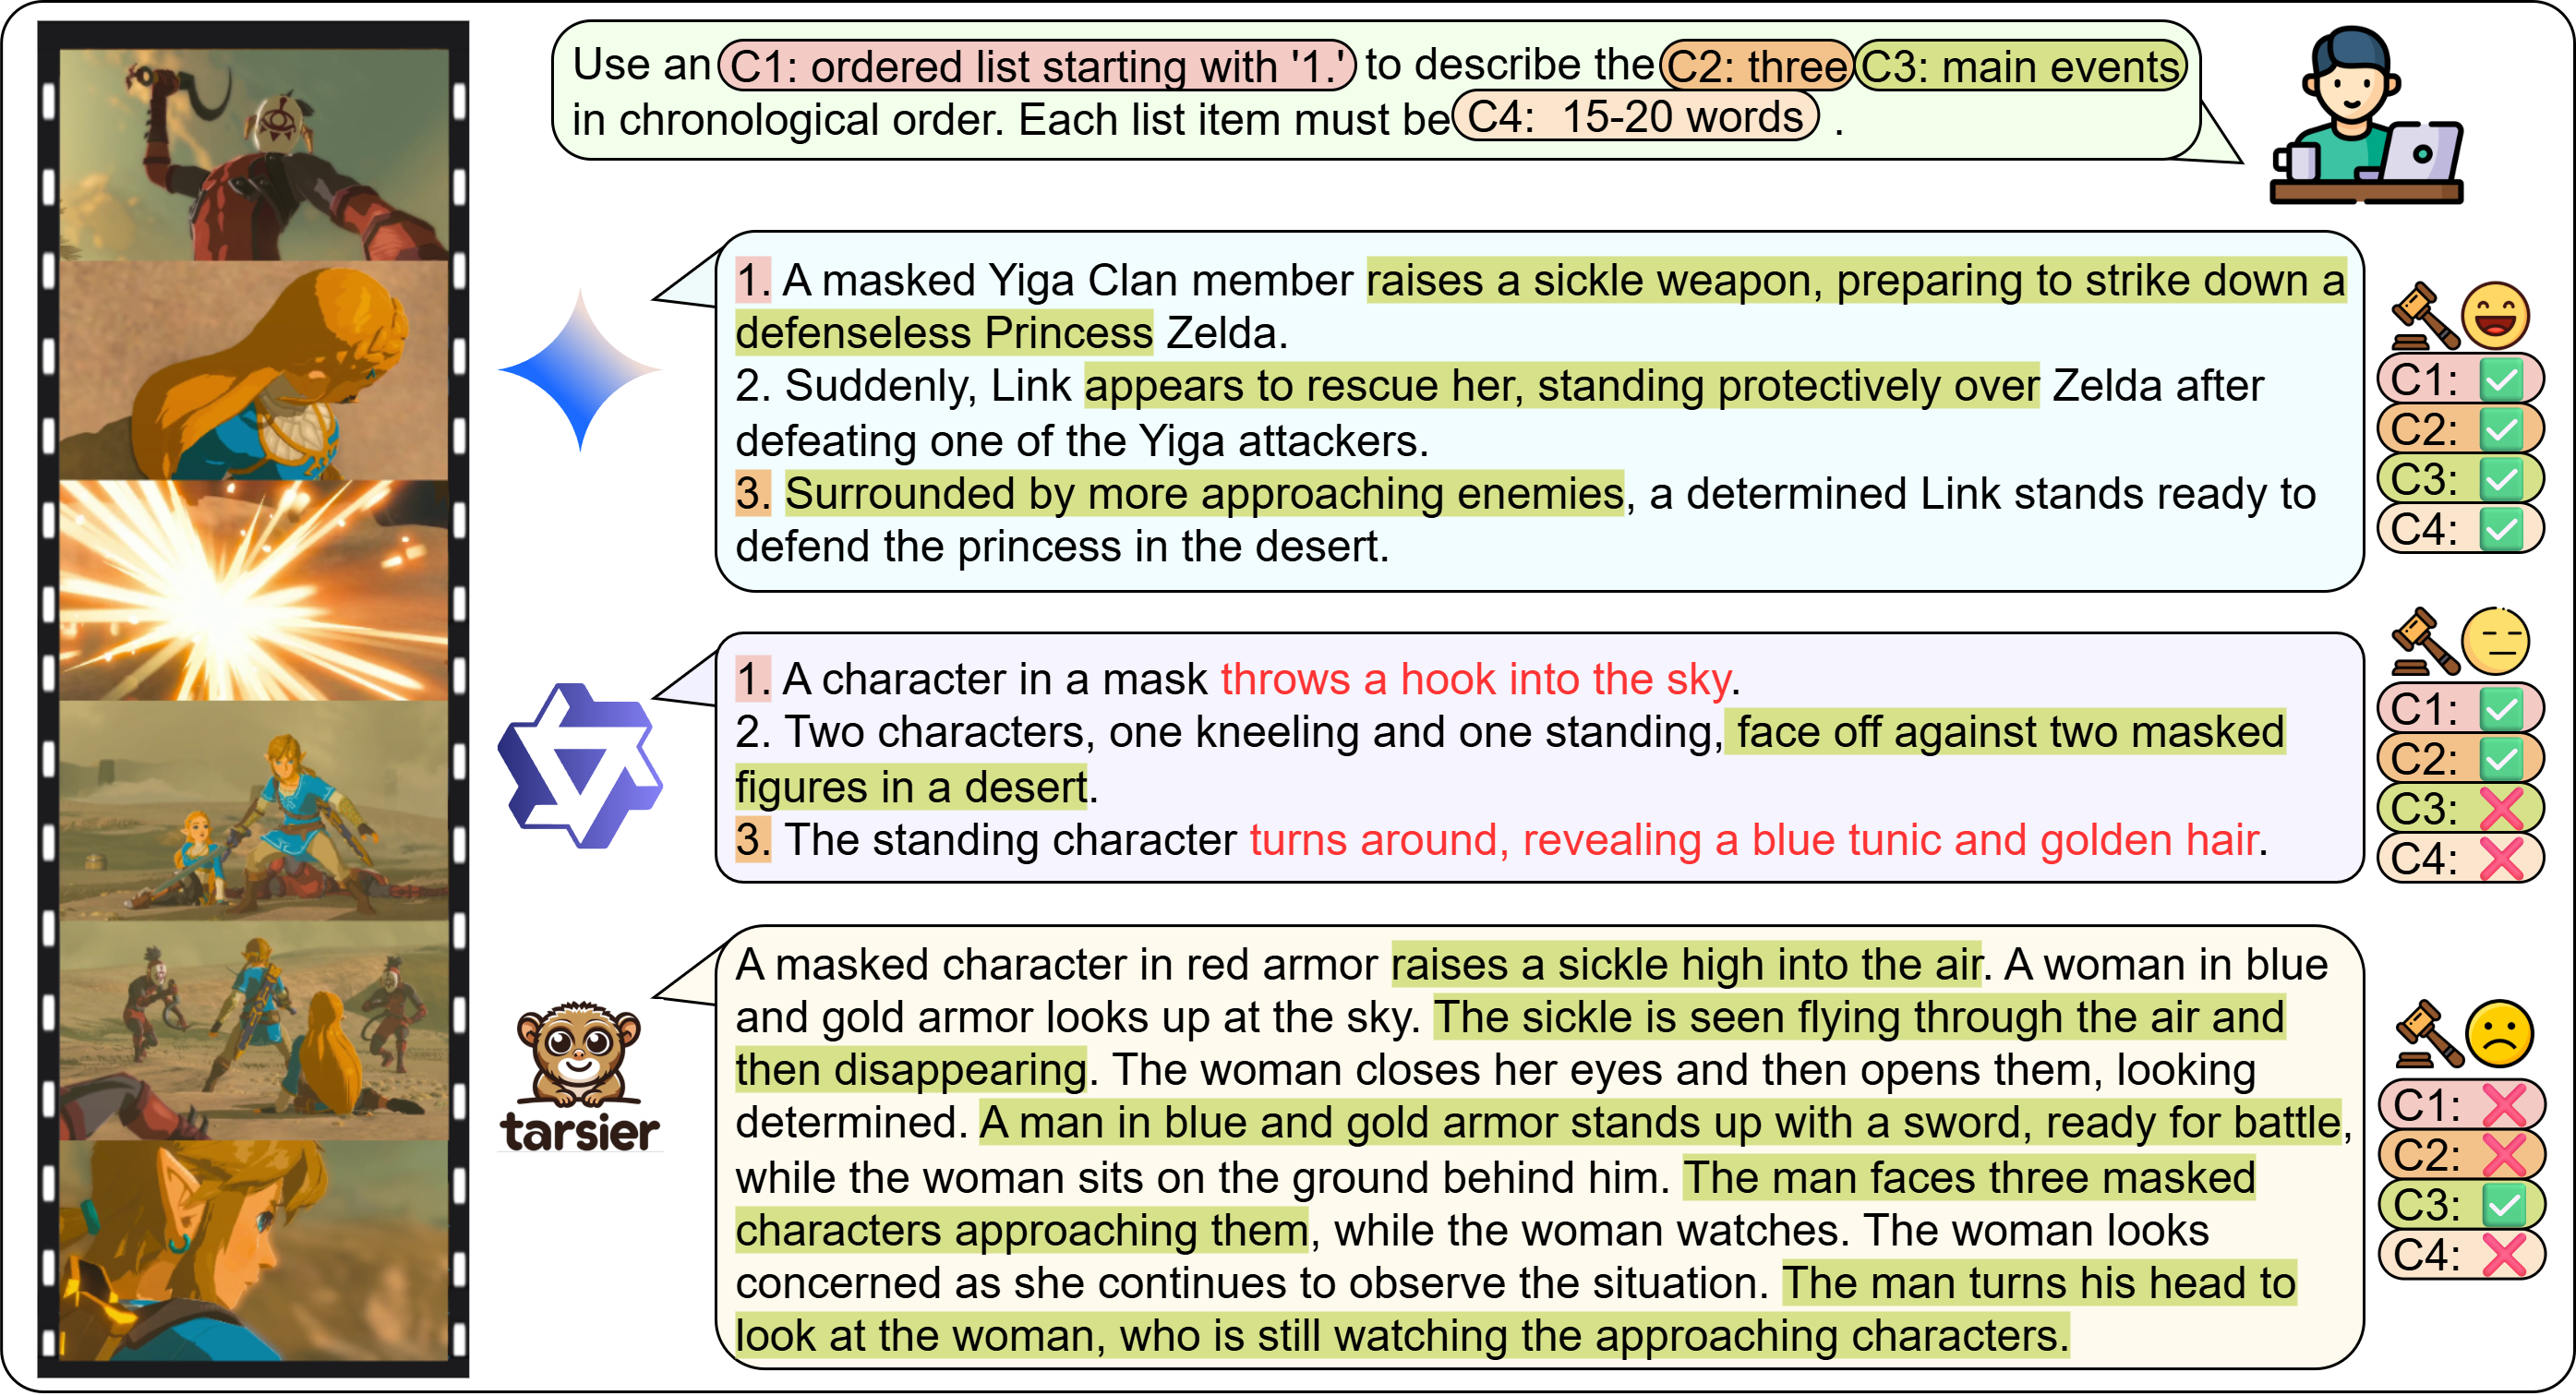
IF-VidCap 对比视频描述模型遵循格式与内容指令的表现

ICLR 2026

IF-VidCap: Can Video Caption Models Follow Instructions?

Shihao Li*, Yuanxing Zhang*, Jiangtao Wu*, Zhide Lei*, Yiwen He, Runzhe Wen, Chenxi Liao, Chengkang Jiang, An Ping, Shuo Gao, Suhan Wang, Zhaozhou Bian, Zijun Zhou, Jingyi Xie, Jiayi Zhou, Jing Wang, Yifan Yao, Weihao Xie, Yingshui Tan, Yanghai Wang, Qianqian Xie, Zhaoxiang Zhang, Jiaheng Liu

Co-author

  • Controllable video captioning. 1,400 samples combine compositional instructions with rule-based and QA checks for format and content.
  • Beyond descriptive richness. Evaluation of 26 models shows that dense-captioning specialists lag behind general-purpose models on complex instructions.

Honors

  • 2026
    National Scholarship, Ministry of Education of China